



A Spark out of memory error is the most common reason Spark applications slow down or fail. This guide covers where Spark runs out of memory, what causes it at each level, and the fixes that work on YARN, Kubernetes, Databricks and Amazon EMR.
Quick definition
A Spark out of memory (OOM) error happens when a driver or executor needs more memory than it has been given. The JVM throws java.lang.OutOfMemoryError, or the cluster manager kills the container for going over its memory limit. The job slows down while Spark spills and retries, then fails if the retries run out.
Why Spark apps slow down or fail
Spark applications are easy to write and easy to understand when everything goes according to plan. Troubleshooting gets hard once they start to slow down or fail. A well-tuned application can fail after a change in the data or its layout. One that ran cleanly for months can start behaving badly because of resource starvation. (For the wider picture, see The Biggest Spark Troubleshooting Challenges.) Teams need to understand the runtime underneath the application, not just the code, to make good decisions when things go wrong.
This two-part series covers the most common reasons a Spark app slows down or fails. Part 1 covers memory management, because when engineers ask why Spark is so slow, a Spark out of memory condition is usually somewhere in the answer. Spark's architecture is memory-centric, so almost every team hits OOM eventually. The most common causes:
- Incorrect usage of Spark, such as pulling large results back to the driver
- High concurrency on each executor
- Inefficient queries that read more data than they need
- Incorrect memory configuration for the workload
Spark's default configuration may or may not fit a given application. Even a well-tuned job can hit a Spark out of memory error after the underlying data grows or changes shape.
Out of memory issues show up in three places: the driver, the executors and the container that hosts them. Here is each one.
Out of memory at the driver level
The driver is the JVM where the application's main control flow runs. Spark is an engine for distributing work across worker machines, so the driver should act as an orchestrator, not a place to process data. In most deployments it gets less memory than the executors. When the driver runs out of memory, it is usually because the code asked it to hold data it was never meant to hold.
Common causes of a Spark driver out of memory error:
collect()ortake()on a large dataset, which pulls every row into driver memorytoPandas()in PySpark, which does the same and then builds a pandas DataFrame on top of it- Broadcast joins, where the build side of the join is collected to the driver, turned into a hash table, then sent to every executor
spark.driver.maxResultSizeset too high (the default is 1g), which removes the safety net that stops oversized results- Driver memory that is too small for the application, or many notebooks sharing one driver on an interactive cluster
- Listing very large numbers of small files, since file listing and planning happen on the driver
The error message usually tells you which one you hit. Total size of serialized results of N tasks is bigger than spark.driver.maxResultSize means a result was too large to bring back. The Databricks knowledge base recommends refactoring the code first and raising the limit only with caution, since a very high value just moves the failure to a java.lang.OutOfMemoryError: Java heap space.
The fix is almost always the same pattern: keep the data on the cluster. Write results to storage from the executors instead of collecting them. Use limit() before toPandas(), or aggregate first so only the summary comes back. On PySpark, Apache Arrow makes toPandas() far more efficient, and Spark 4.2 turns Arrow on by default.
// Inefficient: pulls every row into driver memory
val result = dataFrame.collect()
saveToFile(result)

// Better: executors write the output directly
dataFrame.write.parquet("/path/to/output")
Broadcast joins deserve their own mention. spark.sql.autoBroadcastJoinThreshold defaults to 10MB, and Adaptive Query Execution can also convert a join to a broadcast join at runtime. If the driver runs out of memory while broadcasting, increase driver memory or lower the threshold so Spark uses the more memory-friendly sort merge join.
One more point surprises a lot of teams. More driver memory is not always the answer. Databricks documents a case where the message “The spark driver has stopped unexpectedly and is restarting” comes from long garbage collection pauses, and a bigger heap makes those pauses longer. Refactoring so the driver holds less is the durable fix.
For a Databricks-specific walkthrough, see Preventing Databricks Driver Out of Memory Crashes and Resolving Databricks Driver Bottlenecks for Faster Spark Jobs.
[cta-banner]
Out of memory at the executor level
Executor OOM is the most common Spark out of memory error in production. The usual causes are high concurrency, inefficient queries and incorrect configuration. Here is each in turn.
High concurrency
To see why concurrency causes OOM, start with how Spark runs a job.
Spark breaks each job into stages and each stage into tasks. The number of tasks depends on the stage and the data source. In a map stage (the scan phase in SQL), Spark generally follows the source partitions: a table with 2,000 partitions produces 2,000 scan tasks unless partition pruning cuts that down. In a shuffle stage, the task count comes from spark.sql.shuffle.partitions (default 200) for DataFrames or spark.default.parallelism for RDDs.
How many tasks run at once on each executor depends on spark.executor.cores. Every task running in parallel needs its own working memory from the same heap. Raise the core count without raising memory and executors start to fail.
The math adds up quickly. Spark reads files in splits of up to 128MB by default (spark.sql.files.maxPartitionBytes). Ten tasks running in parallel need at least 1.28GB just to hold their input, before decompression, which can expand the data several times over.
Columnar formats add more. Spark reads Parquet in a vectorized format, batch by batch, one column at a time. Each task holds a batch of rows for every column it reads (spark.sql.parquet.columnarReaderBatchSize, 4,096 rows by default), plus the state for encodings like dictionary encoding. Very wide or deeply nested rows multiply that cost, and more concurrent tasks multiply it again. A broadcast join on the same executor adds the broadcast table on top.
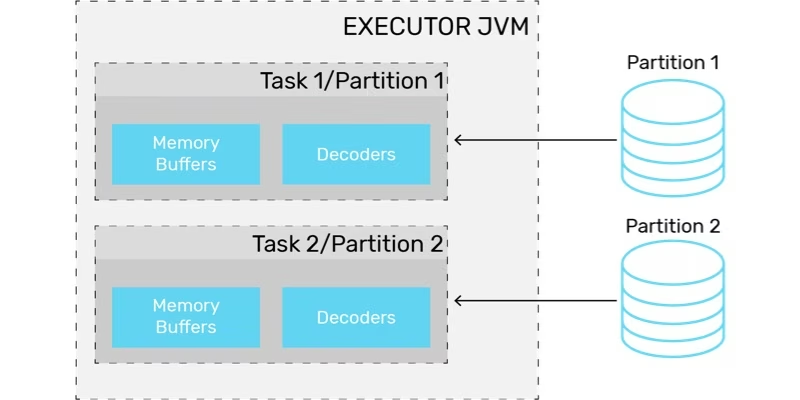
Figure: Spark task and memory components while scanning a table
The fixes: lower spark.executor.cores, give each executor more memory, or increase the number of partitions so each task handles less data. Spark's own tuning guide still recommends two to three tasks per CPU core and lists more parallelism as the first fix for reduce-side OOM. Adaptive Query Execution, on by default since Spark 3.2, now coalesces small shuffle partitions automatically, which takes some of the guesswork out of choosing a partition count.
Inefficient queries
Spark's Catalyst optimizer does a lot to improve a query, but it cannot fix a query that asks for too much. Selecting every column from a wide Parquet or ORC table is the classic example. Each column needs its own in-memory batch, so more columns means more memory per task.
Read only the columns you need. Filter as early as possible so less data reaches the executors. When a table is partitioned, write queries that filter on the partition columns so Spark can skip whole partitions. The Spark 3.0 Performance Impact of Different Kinds of Partition Pruning goes deeper on how pruning works.
Incorrect configuration
Incorrect memory and caching configuration causes a large share of Spark out of memory failures. Four settings matter most.
Executor and driver memory
Every application needs different memory settings. spark.executor.memory and spark.driver.memory have to match the workload, and getting them right is harder than it sounds. It takes measurement, not guesswork. Since Spark 3.1, the Executors tab in the Spark UI shows peak JVM heap and off-heap memory per executor, and the monitoring REST API exposes the same metrics.
On Databricks, executor memory comes from the instance type you choose. Databricks runs one executor per worker, and its compute best practices recommend choosing larger or memory-optimized instances over hardcoding spark.executor.memory. 5 Reasons Under-Provisioned Databricks Clusters Go Unnoticed covers what happens when that choice is off.
Memory overhead
Sometimes the heap is fine and the container is not. Overhead memory is memory outside the JVM heap: JVM internals, interned strings, native libraries and, for PySpark, the Python worker processes.
The 2019 setting spark.yarn.executor.memoryOverhead was deprecated in Spark 2.3. The current settings:
spark.executor.memoryOverheadandspark.driver.memoryOverheadset the overhead directly- The default is 10% of executor memory (
spark.executor.memoryOverheadFactor), with a minimum of 384MB - On Kubernetes, non-JVM jobs such as PySpark default to 40%, because they commonly fail with “Memory Overhead Exceeded” errors
spark.executor.pyspark.memorycaps Python worker memory; when it is not set, Python workers draw from overhead with no limit
Here is how an 8GB executor adds up with default settings:
| Memory region | How it is calculated | Size |
|---|---|---|
| Reserved memory | Fixed | 300MB |
| Unified memory (execution + storage) | 0.6 × (8,192MB − 300MB) | ~4,735MB |
| Storage protected from eviction | 0.5 × unified | ~2,368MB |
| User memory | Remaining 40% | ~3,157MB |
| Memory overhead | max(384MB, 0.10 × 8,192MB) | ~819MB |
| Container request | Heap + overhead (+ off-heap + PySpark memory, if set) | ~9GB |
That last row is the one that matters to the cluster manager. Off-heap memory (spark.memory.offHeap.size) and PySpark memory are added on top of the heap, so enabling them without sizing the container is a fast route to a killed executor.
Caching memory
Applications that cache datasets need to account for Spark's memory manager. It is written to serve every workload, so it has several knobs.
Spark splits its managed memory into two kinds. Storage memory holds cached data. Execution memory holds temporary structures such as the hash tables used for joins and aggregations.
Both come from one pool: spark.memory.fraction of the heap minus 300MB. The default fraction is 0.6. Within that pool, spark.memory.storageFraction (default 0.5) sets how much cached data is protected from eviction. Each side can borrow from the other when memory is free. Execution can evict cached data down to the protected amount, but storage can never evict execution.
If cached data does not all need to sit in memory, lower spark.memory.storageFraction so more of it gets evicted and execution has room to work. To Cache or Not to Cache RDDs in Spark covers when caching helps and when it just takes memory away from execution. For a full tour of Spark's memory regions, see The Guide To Apache Spark Memory Optimization.
For more on executor failures on Databricks, see Preventing Databricks Executor Out of Memory Failures at Scale.
Out of memory at the container level
Some failures never produce a Java error at all. The cluster manager sees a container using more memory than it was allotted and kills it.
On YARN, the error reads Container killed by YARN for exceeding memory limits, and the NodeManager log shows the kill itself:
[pid=<pid>,containerID=<container_id>] is running beyond physical memory limits. Current usage: 1.5 GB of 1.5 GB physical memory used; 4.6 GB of 3.1 GB virtual memory used. Killing container
AWS's guidance for Amazon EMR works through fixes in order:
- Increase memory overhead gradually, up to about 25%
- Reduce the number of executor cores
- Increase the number of partitions
- Increase driver and executor memory as a last resort
On Kubernetes, the pod shows OOMKilled. In both cases, exit code 137 means the process was killed for running out of memory. Both point at memory outside the heap: overhead, off-heap or Python.
YARN has one more layer. When the external shuffle service runs inside the YARN NodeManager, heavy shuffle workloads can push the NodeManager itself out of memory. Its heap defaults to about 1GB (YARN_HEAPSIZE), and the Spark on YARN docs recommend raising it for shuffle-heavy jobs.
The shuffle service matters less than it used to. Spark 3.4 and later turn on shuffle tracking by default, so dynamic allocation no longer requires it. Kubernetes does not support it at all, and managed platforms like Databricks handle this layer for you.
Common Spark out of memory errors at a glance
| Error message | Where | Likely cause | First fix |
|---|---|---|---|
java.lang.OutOfMemoryError: Java heap space | Driver or executor | Heap too small for the data a task or the driver holds | Find the operation holding the data; add partitions or memory |
Total size of serialized results ... is bigger than spark.driver.maxResultSize | Driver | collect(), toPandas() or a large result | Keep results on the cluster; aggregate or limit first |
Not enough memory to build and broadcast the table | Driver | Broadcast table larger than expected | Lower the broadcast threshold or add driver memory |
Container killed by YARN for exceeding memory limits | Executor container | Overhead, off-heap or Python memory | Raise memory overhead; reduce cores |
OOMKilled / exit code 137 | Pod or container | Same as above, on Kubernetes or EMR | Raise the overhead factor; set spark.executor.pyspark.memory |
The spark driver has stopped unexpectedly and is restarting | Databricks driver | Long GC pauses from too much data on the driver | Refactor to push work to the cluster |
Part 2 covers the other two big causes of slow and failing Spark jobs: data skew and garbage collection.
[cta-banner]
Frequently asked questions
What causes a Spark out of memory error?
Usually one of four things: pulling large results to the driver, running too many tasks per executor, reading more data than the query needs, or memory settings that do not match the workload. Growth in the data can turn a healthy job into a failing one without any code change.
How do I tell if the OOM is on the driver or an executor?
Check the error and where it was logged. Driver failures show up in the driver log and often mention maxResultSize or a broadcast. Executor failures show up as lost executors or failed tasks in the Spark UI, often alongside a container kill.
What is memory overhead in Spark?
Memory reserved outside the JVM heap for JVM internals, native code and Python workers. It defaults to 10% of executor memory with a 384MB minimum, or 40% for non-JVM jobs on Kubernetes.
How do I fix “Container killed by YARN for exceeding memory limits”?
Raise spark.executor.memoryOverhead gradually, reduce executor cores, and add partitions. Increase executor memory only after those.
Does adding more memory always fix a Spark out of memory error?
No. It can hide the cause for a while, and on the driver a larger heap can make garbage collection pauses longer. Fixing the code or the partitioning is usually the lasting fix.
Why memory settings alone don't prevent failures
Memory is where the symptom shows up, not always where the problem starts. Adaptive Query Execution, Photon on Databricks and managed compute now handle much of what teams once tuned by hand. What no default can know is that a table doubled overnight, or that a notebook started calling toPandas() on a full dataset.
That is the enterprise-scale challenge. One job is easy to tune. Thousands of jobs drift out of tune one at a time, and the first sign is usually a failure.
How Unravel fits in
Unravel gives teams the visibility to catch memory problems before they become failures. It provides automatic root cause analysis for Spark applications, with insight into misconfiguration, parallelism, partitioning, garbage collection, caching and container resource utilization, so engineers see which job, stage and setting is responsible instead of digging through logs.
On Databricks, Arvix, Unravel's AI engine, goes further: it rewrites inefficient code and rightsizes compute, validates every change against real workload behavior before applying it, and rolls it back automatically if anything degrades. Teams choose how much to automate, from human approval to AutoApply. Unravel's DataOps Agent cuts troubleshooting time by 99%.
See how Unravel makes Spark perform better and more reliably, or request a free health check to find the memory issues in your environment.